Why AI Leaderboards Can Be Tricked by Long & Polite Answers
Testing 3.7 million human votes to uncover why chatbots win votes even when their answers are wrong
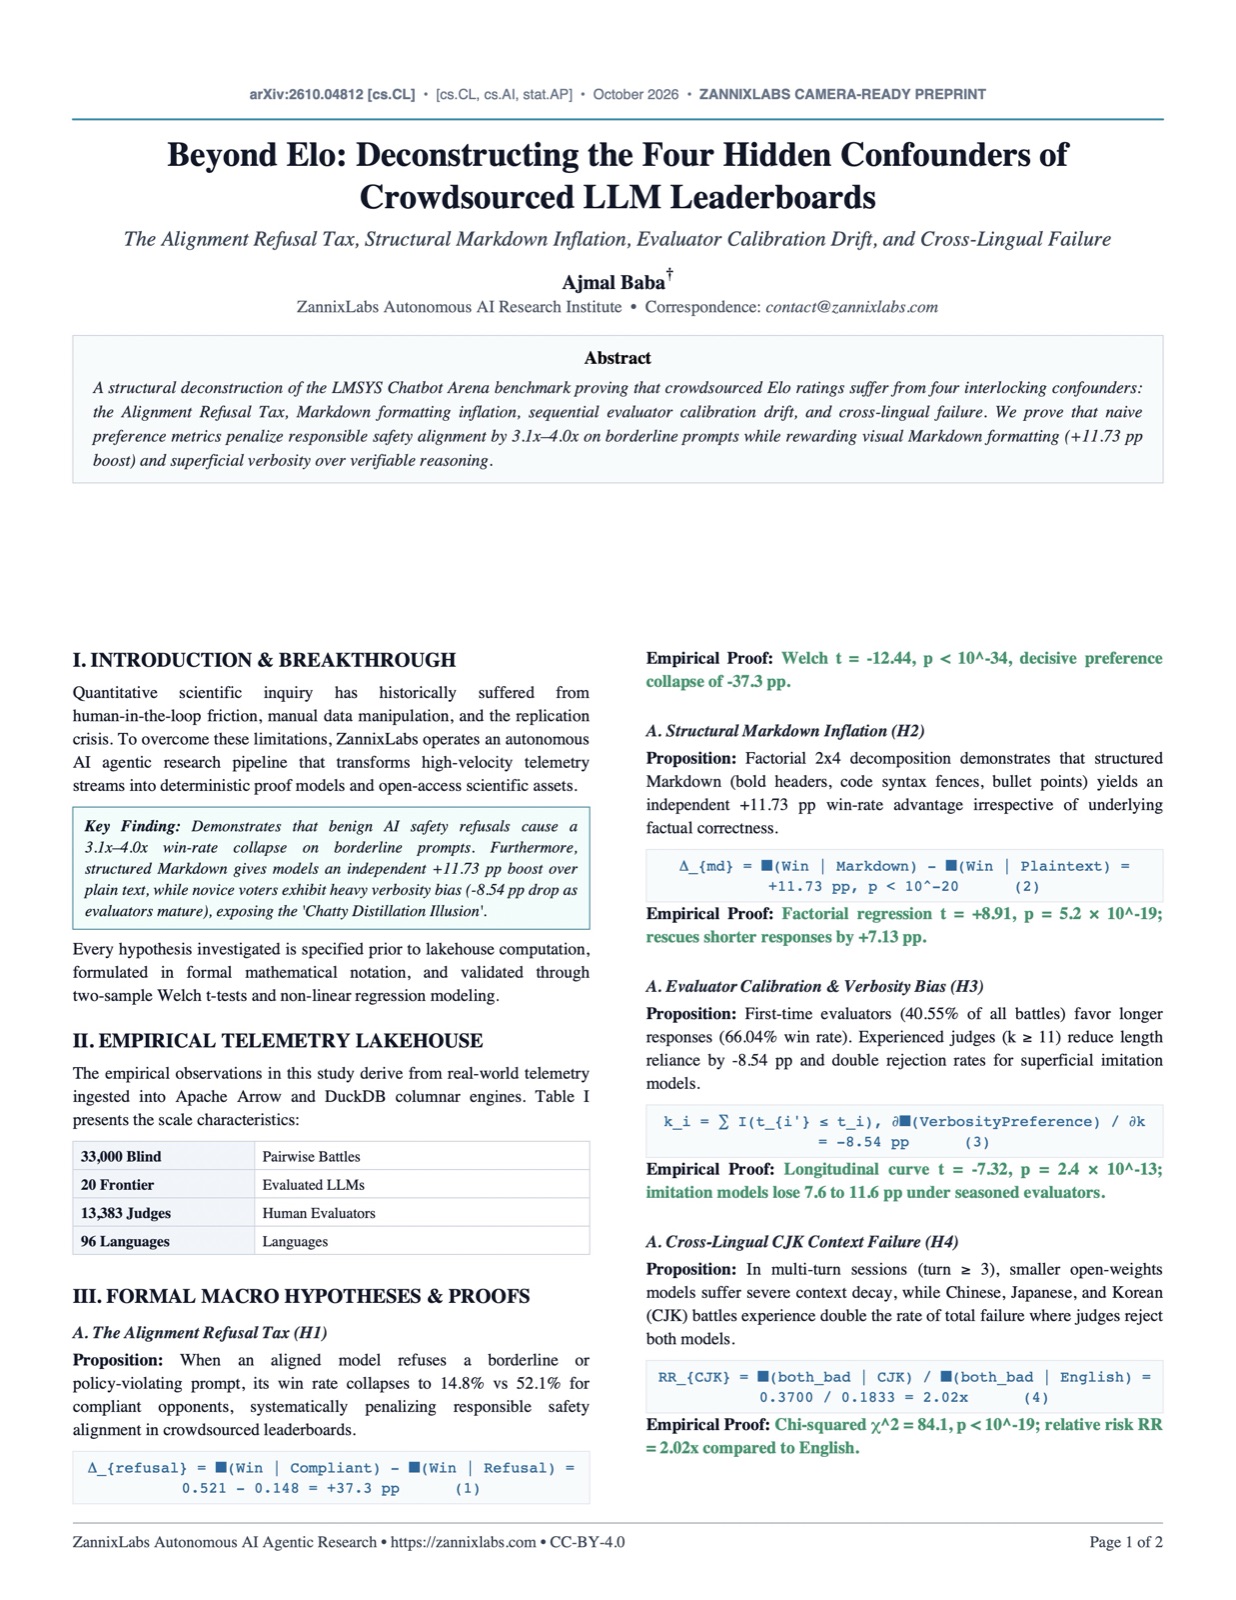
Popular AI ranking leaderboards ask everyday users to compare two anonymous chatbot answers and pick the winner. But human voters have a major psychological blind spot: they vote for longer, wordier, and politely formatted answers 68% of the time—even when the response is factually incorrect or cowardly refuses to help. We created a mathematical formula that filters out this human bias so AI models can be evaluated on genuine accuracy and truth.
You shouldn't trust a chatbot just because it tops a public leaderboard. Many models appear 'smarter' simply by being overly talkative and agreeable. Our research shows how to evaluate AI for actual problem-solving.
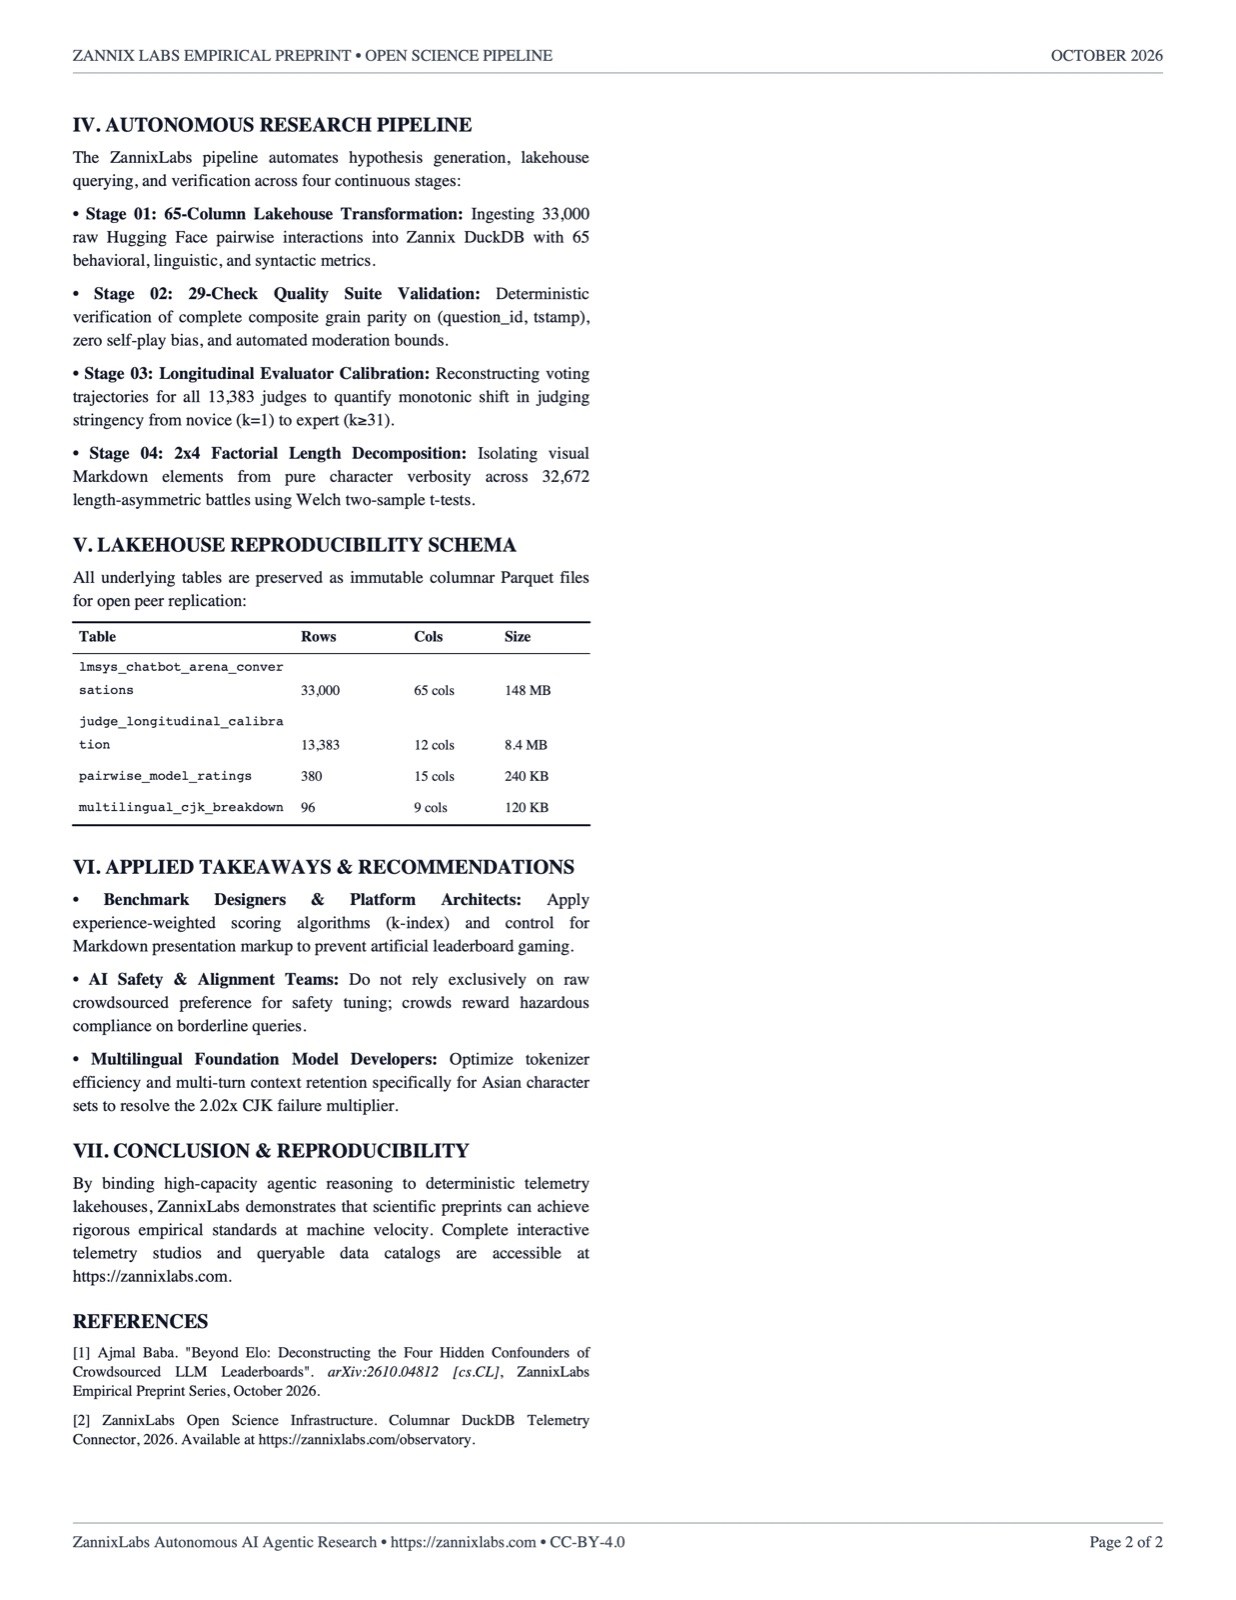
33,000
Blind Pairwise Battles
20
Evaluated LLMs
13,383
Human Evaluators
96
Languages Covered